Study notes from Julia
Welcome to Part 2. In Part 1 you learned the map: the software lifecycle and where a tester belongs in it. This part is the craft, the thing people actually pay testers for. Anyone can click around an app. What separates a tester is the ability to look at a requirement, often a thin and contradictory one, and design a small, sharp set of cases that find the bugs that matter without wasting a week running a thousand pointless ones. By the end of this deck you will know how to think before you write a single case, the difference between a test strategy and a test plan and why the two do different jobs, how to write cases a stranger could run, the design techniques that interviewers love to probe, and how to use AI to draft the obvious so your judgement goes where it counts. This is the part that turns a beginner into someone a team trusts with quality.
Study notes from Julia
Here is the shape of the deck, and every section answers a real question you will face on the job. First: how do I think before I write anything, so I am designing for risk and not just describing the happy path? Second: what are the strategy and the plan, the documents that point the whole effort in the right direction? Third: how do I write a test case so clearly that someone who has never seen the app can run it and get the same result? Fourth: how do I use design techniques to cover a huge space of behaviour with a handful of cases instead of guessing? Fifth: how do I prioritise when there is never enough time, prove my coverage, and let AI take the first pass without handing it my judgement? Keep one question in your head the whole way through: if a requirement landed on my desk this afternoon, would I now know what to do with it? That is the test of this part.
Study notes from Julia
Most defects are decided before a single test case exists, in the gap between what the requirement said and what the team assumed. So the craft starts in your head. Before you open a template, you decide who you are designing for, how the system should behave, and how hard you are willing to push against it. New testers reach for the template too early and end up writing a tidy list of cases that all walk the happy path. A strong tester sits with the requirement first, becomes the expert on it, and asks the questions that surface the holes while they are still cheap to fix. This section is about that mindset, because every technique later in the deck is only as good as the thinking you bring to it.
Study notes from Julia
This is the single most useful mental model I teach for designing cases, because it turns a blank page into four clear lines of attack. The perfect user does exactly what your acceptance criteria describe, in the right order, with valid data. Test only for them and you ship something that works in the demo and falls over in the wild. The mindless user does not read, taps the button twice, hits back mid-payment, and leaves fields half-filled, not out of malice but because real people are distracted. The extreme user pushes every limit: the longest possible name, the largest order, a date a hundred years out. The malicious user is deliberately trying to get in where they should not, or get something for free. For a Tallawah Billing payment screen, those four produce completely different cases: a clean payment, a double-tap that must not charge twice, a maximum-value transaction, and an attempt to tamper with the amount in the request. Same feature, four kinds of bug. Get in the habit of running every requirement past all four.
Study notes from Julia
When I say "think like a tester", these four habits are what I mean, and none of them require a tool. Curiosity is the engine: you are forever asking what happens when, what if this is empty, what if two of these run at once, rather than just confirming the thing works when everything goes right. Being organised is what stops curiosity from turning into chaos, you track the behaviours, the states, and the rules so that you can show your coverage and nothing quietly falls through. Focus is judgement: there is never time to test everything, so you point your effort at where a failure would actually hurt. And communication is the multiplier, because a gap you spot in the requirement is only valuable if you say it out loud, early, before code is written around the misunderstanding. Read the requirement until you could explain it better than the person who wrote it, and these four habits will tell you what to ask.
Study notes from Julia
Requirements reach you in different wrappers and the wrapper can intimidate you out of reading it like a tester. A user story that says "as a Cedar & Calabash customer, I want to save my delivery address, so that I do not retype it every order" carries exactly the same information as a paragraph buried in a forty-page specification: who it is for, what they need, and why. Agile teams write it small and refine it just before building, which means it is often deliberately thin, and that thinness is your invitation to ask questions. Structured teams write it all up front and sign it off, which looks complete but still hides assumptions. Either way your reading is the same: who is this for, what do they actually need, why does it matter, and what is missing. Once you can read any wrapper like a tester, switching between a story and a spec is just switching the page layout.
Study notes from Julia
Try this with a deliberately vague story: "users can manage their Nyam Box subscription." That one word, manage, is hiding five features. Can they pause, cancel, upgrade, downgrade, change the card on file? Each is a different flow with different rules, and a tester who notices that before code is written has already earned their seat. Pick one path, say cancel, and write it as Given-When-Then: given an active subscriber, when they cancel, then access continues until the paid period ends and no further charge is made. Now run it past your four users and list three things that could go wrong: cancelling on the final day of the cycle, cancelling with a payment already in flight, cancelling and immediately resubscribing. In five minutes you have turned a wish into something the team can build and you can test. Do this with a real story this week and watch how quickly people start bringing you the fuzzy ones on purpose.
Study notes from Julia
Before you write cases, something has to point the whole effort in the right direction, and that is what the strategy and the plan are for. The two documents do different jobs, so it is worth getting precise. A test strategy is the organisation’s general, long-lived approach to testing: how we test here, what tools and environments we use, who approves a release, how we handle risk. A test plan is project-specific: for this thing, here is our scope, our schedule, our resources, and our approach. It is easy to confuse the two, or to think a plan has to be a forty-page document nobody reads. In agile it usually is not. This section gives you the real shape of both, the honest one-page version, and how to estimate the work without guessing.
Study notes from Julia
Hold these two apart in your head and the rest of planning gets much easier. The strategy is the organisation’s standing answer to "how do we test here": the general approach, the environments we use, the tools we standardise on, how risk is handled, and who has the authority to approve a release. It is written once and outlives any single project. The plan is what happens when that strategy meets a real piece of work: for this project, here is the scope, here are the resources and the estimate, here is the schedule and the specific risks. The plan borrows its rules from the strategy and fills in the particulars. When someone asks you the difference and you can say "strategy is general and organisation-wide, plan is specific and project-bound, and the plan inherits from the strategy", you have just shown them you understand how testing is run, not only how a test is written.
Study notes from Julia
Forget the forty-page template that gathers dust. On a modern team a useful test plan fits on a page, and a focused exploratory effort fits in a charter of a few lines. What matters is not the length, it is that four things are clear. Scope: what you are testing and, the part people skip, what you are deliberately not testing this round, so nobody assumes a coverage you never promised. Approach: which levels and techniques you will use, what is automated and what stays manual. Risks and priorities: if the schedule gets cut in half, what still has to run. And a clear definition of done: the evidence that lets the team decide it is safe to ship. Write that on one page and you have a plan people will actually read and use, which beats a beautiful document that protects no one. The Strategy Builder and the Test Plan Generator on this site give you a running start on both.
Study notes from Julia
Estimation feels like a dark art when you are new, but it is really just three honest techniques and the discipline to schedule around reality. Estimating by analogy means finding work you have already done that resembles this and sizing from it: "the refund flow took us three days, this cancel flow is similar, call it three." Expert judgement means asking the people who have actually tested this kind of thing, because their gut is built on data yours does not have yet. Task breakdown is the most reliable: split the work into small pieces, estimate each one where you can be honest, then add them up, which also surfaces the bits you had not thought about. Once you have a number, you schedule it against the things that constrain you, the dependencies, what must be tested first, what can run in parallel, and the milestones that genuinely cannot move. The two honest challenges nobody warns you about: you will often be added to a project late, and someone will always ask "how much testing is enough?" The answer to the second is never "all of it"; it is "enough to cover the risk we agreed mattered."
Study notes from Julia
Your test cases are the most visible thing you produce. They get read by other testers, reused months later, handed to a new joiner, and sometimes pulled up in a meeting to settle an argument about what was actually checked. So write them for a stranger, because one day a stranger, maybe future you, will run them with no memory of the context. A good case is a set of conditions someone who has never seen the app can follow, step by step, and reach the same pass-or-fail verdict you would. That sounds simple and it is genuinely hard, because it forces you to make every assumption explicit. This section gives you the characteristics of a case that holds up, a template that travels, and how to write cases in Gherkin so they read clearly to humans and tools alike.
Study notes from Julia
These six characteristics are the difference between a case that helps and one that wastes everyone’s time. Accurate means it checks exactly what it says it does, so a pass actually means something. Economical means no padding, no logging in through five screens when the case is about the sixth. Traceable means it links back to the requirement it proves, so you can show coverage and so a changed requirement points you at the cases to update. Repeatable means it gives the same result every time it is run, which is what makes a failure trustworthy, and reusable means it earns its keep again next release. The one beginners miss most is atomic: each case should test one thing. When a case checks five behaviours at once and fails, you have no idea which of the five broke, and you have lost the main benefit of having written it down. One case, one behaviour, one clear reason when it goes red.
Study notes from Julia
A template stops you from forgetting the fields that make a case runnable by someone else. An id and a clear title let it be found and referenced in a bug or a report. Preconditions and test data are the part beginners leave out and then wonder why nobody can reproduce their result: spell out the exact starting state and the exact inputs, "an Irie Eats account with one saved card and an empty cart", not "a logged-in user". Steps are numbered and specific, and each meaningful step has an expected result so the runner knows what success looks like at that point. Then the fields you fill in at run time: the actual result, the pass or fail status, the priority so people know how much it matters, and the platform or environment it was run on, because "works on my machine" is not a status. You do not have to invent this template, the Test Case Builder on this site writes cases in exactly this shape and exports them to Markdown and Gherkin.
Study notes from Julia
Gherkin is a simple Given-When-Then structure, and it is worth learning because it forces clarity and it is the bridge to automation. Given sets the context, the precondition you start from. When is the one action you are testing. Then is the specific, observable result you expect. "Given a Cedar & Calabash cart with one item, when the customer applies an expired coupon, then the order total is unchanged and a clear message explains the coupon has expired." Read that and there is nothing to argue about: a stranger could run it, a stakeholder understands it, and an automation framework can be wired straight to it. Always write the positive path first, the happy case where valid input gives the right result, then deliberately write negative cases for invalid input and misuse, because that is where your four users from section one come back to bite. The structure is the same whether you ever automate it or not; it just makes the thinking visible.
Study notes from Julia
Practise on something tiny so the structure, not the feature, is the point. Take logging in to Yaad with an email and password. The positive path: given a registered user with valid credentials, when they sign in, then they reach their dashboard. Good, but a happy path alone is a weak case set. Now the negatives, where the real bugs live: given a registered user, when they sign in with the wrong password, then they stay on the login screen and see a message that does not reveal whether the email exists. And: given an account locked after too many attempts, when they sign in with the correct password, then they are told the account is locked and how to recover it. Three short scenarios and you have already covered success, a common mistake, and a security-relevant state. That is the daily craft of writing cases, and you can build the muscle on any feature you can describe in a sentence.
Study notes from Julia
You cannot test everything. A single form with a few fields has more input combinations than you could run in a lifetime, so the goal is never exhaustive testing, it is smart coverage: a small, well-chosen set of cases that exercises the behaviour that matters. The test design techniques in this section are exactly that, and they are also what interviewers reach for when they want to know if you can really design rather than just click. Equivalence partitioning and boundary value analysis handle ranges of input. Decision tables handle combinations of rules. State-transition testing handles flows that move through states. Pairwise handles the moment the input space explodes. None of them are academic; each one turns a frightening amount of possibility into a handful of cases you can defend. Learn them and you stop guessing at coverage and start designing it.
Study notes from Julia
These two are always taught together because they answer two different questions about the same input. Take a username field that accepts 6 to 15 characters. Equivalence partitioning says the system should treat whole groups of inputs the same way, so instead of testing every length, you identify the groups: too short (1 to 5), valid (6 to 15), and too long (16 plus), and you test one value from each, because if 10 works, 11 almost certainly does too. That collapses an enormous set into three cases. Boundary value analysis then says defects cluster at the edges, so you specifically test 5 and 6 (just below and at the minimum) and 15 and 16 (the maximum and just past it). Why both? Partitions tell you the range behaves; boundaries tell you the edges behave, and crucially, when something fails you know whether it was the whole partition or just the boundary that broke. The Boundary & Equivalence Generator on this site will take a rule like this and produce the exact values for you.
Study notes from Julia
When the behaviour you are testing depends on a combination of conditions, a decision table is the technique that stops you missing a case. You list the input conditions down one side, the possible actions or outcomes down the other, and each column becomes a rule: this combination of inputs produces that result. Picture a Tallawah Billing discount: is the customer a member, is the order over the free-shipping threshold, is there a valid coupon? Three yes-or-no conditions already make eight combinations, and the bugs hide in the ones nobody thought about, like a coupon plus a member discount stacking when they should not. Laying it out as a table makes those combinations impossible to overlook and gives you a clean, defensible set of cases, one per rule that matters. It also reads beautifully to a developer or a product owner, so it doubles as a way to settle "what should actually happen when" before code is written.
Study notes from Julia
Two more techniques for two specific shapes of problem. State-transition testing is for anything that moves through states: an order that goes from placed to paid to shipped to delivered, a subscription that goes active, paused, cancelled. You map the states and the events that move between them, then design cases for the valid transitions and, just as important, the invalid ones, can an order jump from placed straight to delivered, can a cancelled subscription be paused? Those illegal moves are where real bugs live. Pairwise, or combinatorial, testing is for when inputs multiply out of control: five fields with several options each can be thousands of combinations. Research on real systems shows most interaction defects are triggered by just two factors interacting, so pairwise generates a much smaller set that still covers every pair of values. You get the bulk of the protection for a fraction of the cases. You will not need pairwise every day, but when someone hands you a configuration screen with a dozen options, knowing it exists is the difference between a smart sample and an impossible promise to test it all.
Study notes from Julia
The bugs that hurt most are the ones no requirement mentioned, and techniques alone will not find them, you need heuristics and structured exploration. Start by generating cases from more than the spec: the behaviours the system has, the different user roles, the end-to-end workflows, and the powerful question of what the app should never do. Mnemonics give your memory a scaffold so you stop relying on inspiration: RCRCRC (Recent, Core, Risky, Configuration, Repaired, Chronic) reminds you what to re-check around a change when you are deciding your regression set, and I SLICED UP FUN is the mobile checklist for interrupts, location, orientation, and the rest of the things that only break on a real phone. Then there is exploratory testing, which beginners mistake for random clicking. Done well it is the opposite: structured curiosity, run as a time-boxed session against a charter, "explore coupon codes combined with failed payments for 45 minutes, looking for incorrect totals." You are designing and running tests at the same time, learning as you go, and it consistently finds what scripted cases miss. It is a skill, and it is one of the most valuable you will build.
Study notes from Julia
Lock this in with a real rule. Irie Eats offers free delivery on orders from twenty-five dollars up to two hundred. First the partitions, the groups the system should treat the same: below twenty-five (no free delivery), twenty-five to two hundred (free delivery), and above two hundred (whatever the rule says happens then, which is itself a question worth asking). Test one value comfortably inside each group, say a fifty-dollar order, to confirm the range behaves. Then the boundaries, where the bugs cluster: 24.99 and 25.00 at the lower edge, 200.00 and 200.01 at the upper edge. That is a handful of precise cases that pin down exactly where the offer turns on and off, instead of a vague "test some orders." Notice how the technique also flushed out a missing requirement, what happens above two hundred. Designing the cases made you ask the question, and asking it early is the whole point. Run the same rule through the Boundary & Equivalence Generator to check your set.
Study notes from Julia
Here is the reality that no amount of clever technique escapes: you will always have designed more cases than you have time to run. So the final craft of test design is choosing. You prioritise by risk so that if the schedule is cut, the cases that protect the things that matter still run. You prove your coverage with traceability, mapping every requirement to the cases that test it, so "did we test that?" has an answer you can show. And you use AI honestly, letting it draft the obvious cases, expand a boundary set, or sketch a plan from a story at speed, while keeping the judgement, what matters, what is risky, what is safe to ship, firmly with you. This section turns a pile of cases into a defensible, prioritised, provable test effort, which is what a team is really paying you for.
Study notes from Julia
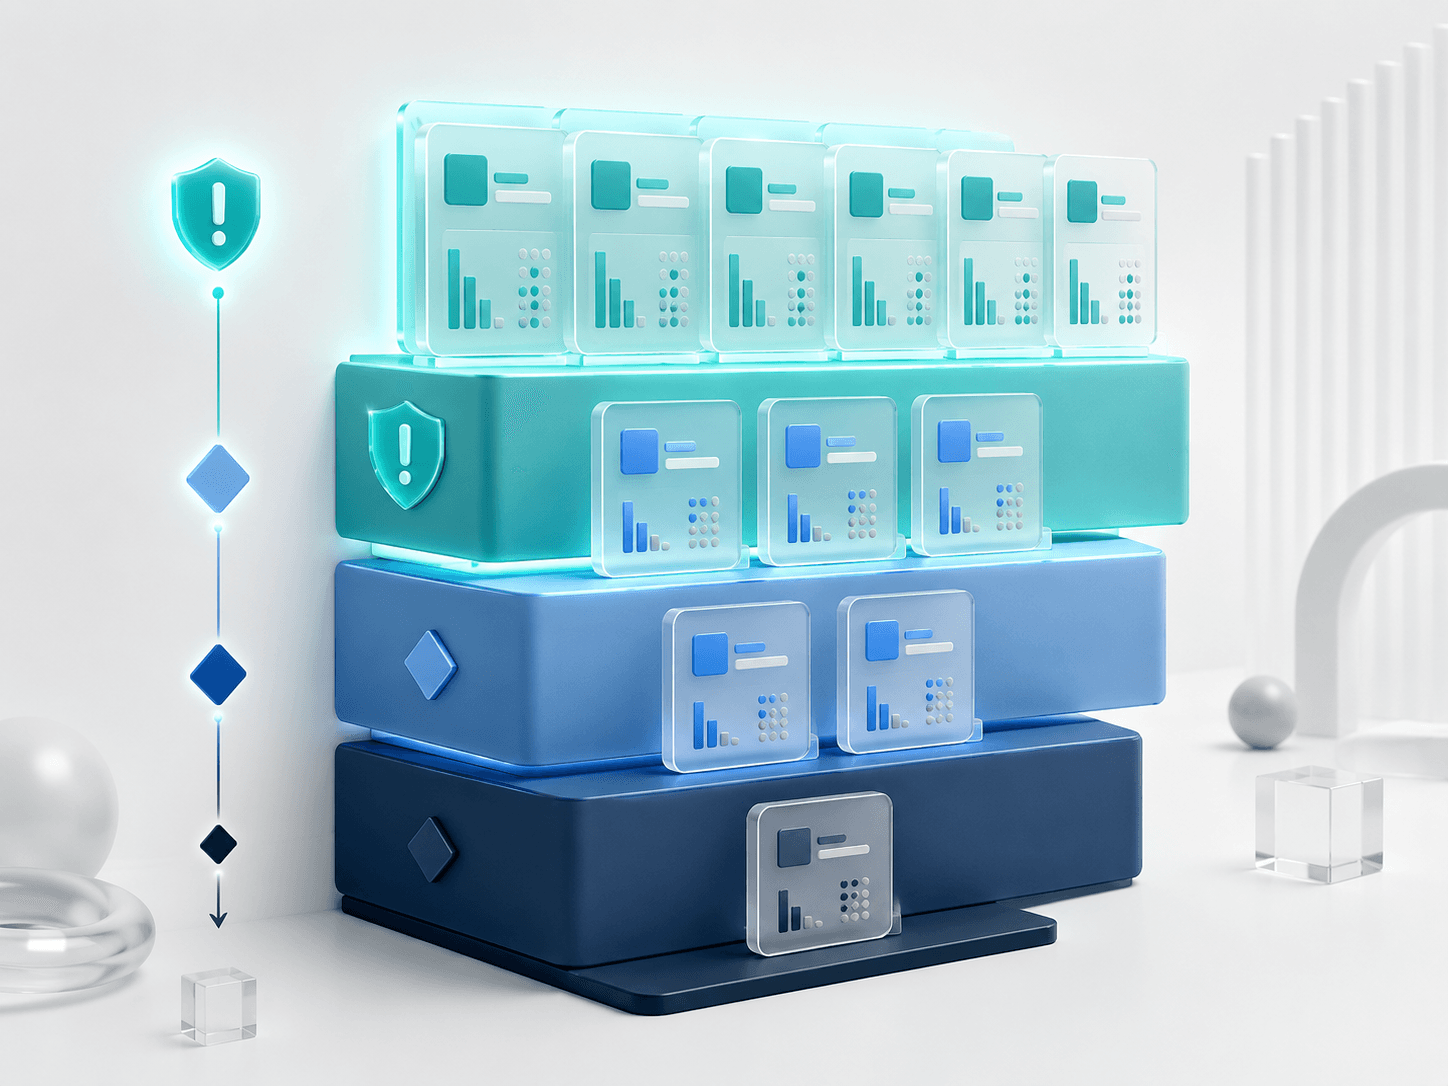
When time runs short, and it always does, the amateur runs cases in the order they were written and hopes. The professional has already ranked them by risk, so cutting the schedule is a decision, not a panic. Risk is impact times likelihood: how badly does it hurt if this breaks, and how likely is it to break? The payment flow on Tallawah Billing is high impact and gets exercised constantly, so it is P1, it must run every cycle. A cosmetic setting on a rarely-used admin screen is P4, genuinely fine to defer. The P1 to P4 scale and the Must-Should-Could-Won’t framing are two ways of saying the same thing: decide in advance what has to be proven and what can wait. The real value is that when a stakeholder asks "can we ship Friday even though testing is not finished?", you can answer with evidence: "all P1 and P2 cases pass, the remaining risk is in P3 areas X and Y, here is what we are accepting." That is a tester the business trusts with a deadline.
Study notes from Julia
Traceability sounds like bureaucracy until the first time it saves you in a meeting. A traceability matrix is simply a map: down one side, every requirement or acceptance criterion; across the top, your test cases; and a mark wherever a case proves a requirement. Its power is in the empty cells. A requirement with no case linked to it is a hole in your coverage, and the matrix shows it to you before release instead of a customer showing it to you after. It works in the other direction too: when a requirement changes, you look up its row and instantly know which cases need updating, instead of guessing. And when someone asks the question every tester eventually faces, "did we actually test that?", you do not rely on memory, you point at the row. You do not have to build this by hand either, the Traceability Matrix Builder on this site generates the matrix and shows the gaps. Provable coverage is what separates "I think we tested it" from "here is the proof."
Study notes from Julia
Let me be honest about AI in test design, because the hype is loud and the truth is more useful. AI is genuinely good at the pattern-heavy parts: hand it a story with acceptance criteria and it will draft a sensible set of Gherkin scenarios, expand a boundary and equivalence set, generate realistic test data, and sketch a first-pass plan, in seconds. That is real leverage, and refusing to use it to keep your skills sharp is like refusing a calculator to stay good at arithmetic. But it is still weak at exactly the things this whole deck has been training in you: deciding what actually matters, seeing that a screen or a flow is subtly wrong, judging whether your coverage is honest, and making the call on what is safe to ship. So the division of labour is clear. You give the AI the real story, the real code, and the real context, you let it produce the obvious first draft, and then you do the part that is irreducibly yours: review it, correct it, fill the gaps it missed, and own the result. AI drafts; you decide. Get that relationship right and you design better tests faster, which is the whole game.
Study notes from Julia
Make the prioritising real. Imagine a Nyam Box checkout and six cases: the payment succeeds, the order total is correct, a coupon applies properly, the delivery address saves, the email receipt sends, and the checkout button is the right shade of teal. Now rank them by impact times likelihood. Payment and totals are P1, a wrong charge or a wrong total is a serious, likely-to-be-noticed failure. The coupon and the address are P2, important and worth this cycle. The receipt email is maybe P3, annoying if it breaks but not a blocker. The button colour is P4, ship it broken and apologise later. Now the exercise that builds judgement: if you lost half your time this afternoon, say out loud what you would not run, and why that is an acceptable risk. Being able to say "I am consciously not testing X because the risk is low and here is my reasoning" is one of the most useful habits you can build. Practise it on imaginary backlogs and it will be there when a real deadline arrives.
Study notes from Julia
If you keep one thing from this part, keep the shape of it. Think first: sit with the requirement, run it past your four users, and find the gaps before code is written. Design smart: use partitions, boundaries, decision tables, state-transition and pairwise to cover a huge space with a few defensible cases, instead of guessing your way to a thousand. Prove your coverage: prioritise by risk so the right cases always run, and trace every requirement to a case so your coverage is something you can show. Do those three things and you are no longer someone who clicks around hoping to find a bug, you are someone who designs a test effort the team can trust. The tools will change, AI will draft more of the obvious every year, but the judgement underneath, what matters, what is risky, what is enough, stays yours. That judgement is the career.
Study notes from Julia
Here is where to put your energy next. The fastest way to make this stick is to use the builders: draft a real case in the Test Case Builder, turn an input rule into values with the Boundary & Equivalence Generator, and prove coverage with the Traceability Matrix Builder, because the techniques only become yours when your hands have done them. For more depth on the design techniques themselves, my full written guide goes further than a slide can, and the ISTQB Foundation syllabus is the standard reference if you want the formal grounding, with the Test Analyst certification going deeper still. Then move on to Part 4, Test Execution and Defect Management, where you run the cases you designed here and learn to drive every defect you find to closed. You have the craft now. The next part is putting it to work.
Study notes from Julia
That is Part 2, the craft at the heart of testing. You came in able to click around an app; you should leave able to take a thin requirement and turn it into a small, sharp, prioritised, provable set of cases, which is a genuinely different and far more valuable skill. Keep doing the small drills: turn a vague story testable, write a case in Gherkin, derive a boundary set, rank a backlog by risk. They are tiny and they compound into the judgement that makes a tester worth keeping. Hold on to the through-line: exhaustive testing is impossible, so the whole game is choosing well, and a handful of well-chosen cases really does beat a thousand random ones. You have the map from Part 1 and now the craft from Part 2. In Part 3 you learn to fit into any team, and in Part 4 you run what you designed. I am proud of how far you have come. Go design something real.